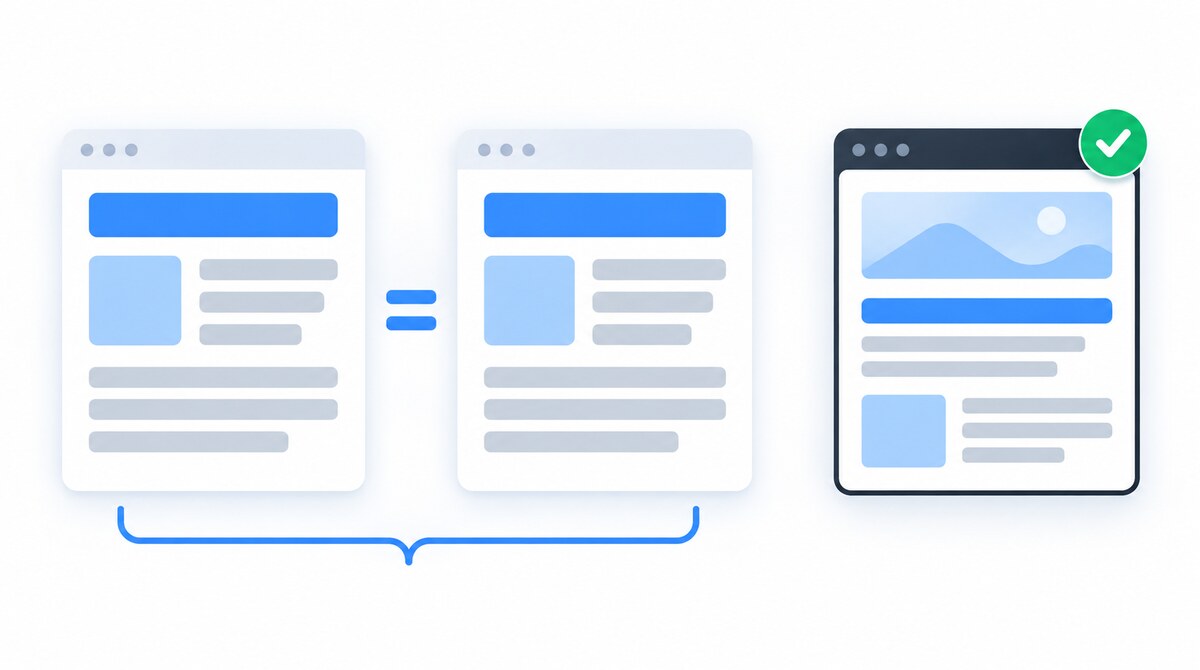
Duplicate content is the same, or substantially similar, main content available at more than one URL. It can happen within your own website or across different websites. It doesn't automatically mean someone copied an article: a tracking parameter, an old address or a second category path can create another version of the same page.
The useful question isn't “How do I remove every repeated sentence?” It's “Do these URLs serve the same purpose, and which ones should people find in search?” This guide helps you answer that before you delete pages or change indexing settings.
What Counts as Duplicate Content?
Compare the main information and the task a page helps someone complete. These two example addresses could display exactly the same service page:
https://example.com/seo-audit/https://example.com/seo-audit/?utm_source=newsletter
The second address records where a visit came from. If it doesn't change the page's main content, it hasn't created a new service or a new article. Two addresses don't necessarily represent two different pieces of information.
Near-duplicates aren't always identical word for word. A different headline or a few swapped adjectives might leave the substance unchanged. Conversely, two detailed guides can discuss the same broad subject while answering different questions.
Google's canonicalization documentation explains that it groups pages with the same or very similar primary content and selects a representative URL. That selected address is called the canonical. If the terminology is new, our beginner's technical SEO guide explains how this fits into crawling and indexing.
Is There a Duplicate Content Penalty?
Ordinary duplicate URLs aren't automatically a Google penalty. Google's SEO Starter Guide distinguishes normal URL duplication from copying other people's content. Having the same page accessible through multiple addresses isn't, by itself, grounds for a manual action.
That doesn't make every form of duplication harmless. Google's spam policies address practices such as abusive scraping and producing large amounts of unoriginal content mainly to manipulate rankings. Those are different from a shop generating a tracking URL for an existing product.
For a legitimate website, the problems to investigate are usually more concrete:
- The wrong address represents the content. Search visitors may reach an outdated or unintended version.
- The website gives inconsistent clues. Navigation, sitemaps and page annotations can disagree about which address is preferred.
- Maintenance becomes harder. Two live copies of a service description can drift apart when only one gets updated.
- Generated URLs multiply unnecessarily. Large parameter combinations can consume crawling resources without adding useful content.
Google discusses the crawling problem in its URL structure guidance. A handful of campaign URLs and an effectively endless set of filter combinations deserve different levels of attention. Don't turn a small duplication report into an emergency without checking its scope.
Common Causes, and Things That Only Look Like Duplicates
Tracking parameters and alternate paths
A product might be reachable from both a sale category and a brand category using different addresses. Campaign parameters, session identifiers and inconsistent URL generation can add more variants. Check what each address actually returns; don't assume every question mark creates a duplicate.
Old URLs and inconsistent site versions
After a redesign, an old service URL may still display the same content as its replacement. HTTP and HTTPS, www and non-www, or slash and non-slash versions can also expose copies if the site serves them separately. Changing the visible menu doesn't necessarily retire the old route.
Repeated templates, titles and descriptions
A shared header, footer or contact block doesn't mean every page is the same. Likewise, a crawler warning about duplicate titles is a metadata finding, not proof that the main content is duplicated. Review those issues separately. Our on-page SEO guide covers page titles and descriptions.
For example, an audit service page and an audit tutorial can share your navigation and author biography while serving different needs. Explain what the customer receives on the service page; teach the process on the tutorial. You don't need to invent a new footer for each one.
Pagination and genuinely different selections
Page two of a product category normally shows different items from page one. It isn't a duplicate just because the layout matches. Google's pagination guidance recommends a separate URL and canonical for each page, rather than pointing every page to the first.
Filters need a deliberate content and crawl strategy. Before deciding to keep a filtered landing page in search, ask whether it has a stable purpose and a useful selection for a specific audience. Don't apply the same rule to a valuable category and every possible sorting combination.
Translations and overlapping topics
Properly translated main content isn't treated as a duplicate merely because it conveys the same information in another language. Google's canonicalization guidance distinguishes translated primary content from pages where only navigation has been translated. International targeting needs its own review.
Two articles sharing a keyword aren't automatically duplicates either. A guide to choosing an audit provider and a checklist for conducting an audit can have distinct jobs. Use search intent to examine the purpose before combining them.
How to Investigate a Suspected Duplicate
Start with a small group of URLs that a tool or report flagged. Save the examples before making changes. My suggested review sheet has five fields: URL, page purpose, main-content comparison, reported canonical and proposed action.
- Open the pages side by side. Compare the actual service, products, instructions or answers. Look past navigation and other repeated layout elements.
- Check their behavior. Does each URL show a page, redirect somewhere else or return an error? Note the final address and HTTP response. The status code guide explains those responses.
- Inspect the declared canonical. Record the preferred address stated by each page, including any unexpected domain or hard-coded destination.
- Compare Google's stored information. In Search Console, inspect the affected URL and its reported canonical. The URL Inspection documentation explains why indexed information and a live test are different; the live test cannot predict Google's canonical choice.
- Find the source of the extra URL. Check menus, category templates, internal links, sitemap entries and CMS routing. Fixing the generator is often more useful than editing each resulting URL.
What the Search Console messages mean
Google's Page indexing report distinguishes several situations:
- Alternate page with proper canonical tag: Google recognizes an alternative version pointing to an indexed representative. If that matches your intention, there may be nothing to fix.
- Duplicate without user-selected canonical: Google selected a representative without an explicit preference from this page. Check whether that choice is suitable.
- Duplicate, Google chose different canonical than user: your preferred address and Google's selection differ. Compare the content and technical signals before changing settings.
The goal isn't to make every discovered URL indexed. It's to make the intended, useful pages available in search. If the preferred page itself is missing, continue with our indexing troubleshooting guide.
Should You Keep, Merge, Redirect or Canonicalize?
Make the editorial decision first: do visitors need both pages? Then choose the technical behavior. This table is a starting point, not a rule to apply blindly across a website.
| Situation | Starting action | Check before release |
|---|---|---|
| Different useful purposes | Keep both and make their roles clear. | Each page delivers its own answer or task. |
| Two overlapping articles | Consider merging useful material. | The combined page preserves what readers need. |
| An obsolete equivalent URL | Use a permanent redirect. | The destination genuinely replaces the old page. |
| A needed duplicate version | Suggest the representative with a canonical. | The pages are equivalent and the target works. |
| A public page unwanted in search | Consider noindex for that goal. | It should be excluded, not consolidated. |
Keep pages when their value is genuinely different
If both pages deserve to exist, improve the actual information that distinguishes them. Add relevant examples, product details, scope or answers. Swapping synonyms to make a similarity score smaller doesn't help a reader choose the right page.
Google's canonical troubleshooting guidance recommends checking technical errors and whether pages grouped together have sufficiently different content. A self-referencing tag alone doesn't explain why an otherwise identical page should be treated separately.
Merge overlapping material, then retire the redundant URL
For two guides serving the same audience and task, review what each contributes before combining them. Choose the destination using relevance, existing links, search data and maintenance needs, not simply whichever URL looks shorter. Preserve useful material and update links that point to the retired page.
Use a permanent redirect when the move really is permanent. Google's redirect documentation lists server-side 301 and 308 responses for that purpose. A redirect changes the destination for visitors too. Don't send unrelated removed pages to the homepage merely to avoid seeing errors.
Use a canonical when equivalent versions must stay accessible
A canonical annotation suggests which equivalent URL should represent the content while leaving the other version available. It isn't a browser redirect or a guarantee that Google will accept the choice. Follow Google's canonical implementation guidance, and use our canonical URL guide for the HTML and testing details.
Make supporting signals consistent: use the preferred address in internal links and the sitemap, and avoid conflicting annotations. Don't point a genuinely different service at a popular article simply because you'd like the article to rank better.
Use noindex only when exclusion is the goal
Noindex asks Google to keep a page out of search. It isn't a way to nominate another page as its representative. For example, a public utility page might need to remain usable without becoming a search landing page.
Google must be able to crawl the page to see its noindex directive. A robots.txt block can prevent that. Don't combine controls without understanding their different jobs, and don't treat noindex as password protection. Our robots.txt guide explains crawl control separately.
A Worked Example: Two Guides Answering the Same Question
This is a hypothetical example, not a client result. A consultancy has an older article called “Website Audit Steps” and a newer one called “How to Audit Your Website.” Both walk beginners through essentially the same process. The older page contains a useful evidence-recording example; the newer one has a clearer checklist.
My first recommendation would be an editorial review, not an immediate canonical change:
- Check whether either article serves a distinct audience or receives searches for a different task.
- If they really overlap, choose one destination and combine the useful example with the clearer checklist.
- Redirect the retired article to the finished replacement, then update relevant internal links and the sitemap.
- Check the live redirect, destination content and subsequent Search Console information.
If the review instead shows that one page helps a business hire an auditor and the other teaches a developer how to run checks, keeping both may be the better decision. Their shared vocabulary isn't the deciding factor.
How to Check Whether the Fix Worked
Separate what you can verify immediately from what requires a later search-engine visit. Record the release date and keep a rollback path for changes to templates or routing.
- Immediately: open the old and preferred URLs, test redirects, inspect canonical and robots directives, and confirm the destination still contains the expected information.
- Across the site: sample other pages using the same template. Confirm that internal links and the XML sitemap reflect the intended page map.
- After reprocessing: revisit indexed URL Inspection data and assess whether the reported representative matches your intention. Google needs time to reevaluate changed pages; don't promise a fixed recovery date.
Keep business outcomes separate from implementation checks. A working redirect is something you can prove. More traffic or inquiries after consolidation is an outcome to measure, not a guaranteed reward. For larger patterns, use the SEO audit checklist to document affected pages, causes and priorities.
Unsure Whether Your Pages Are Duplicates?
I offer a free initial review of a small selection of public pages, with up to five priority findings or next steps by email. A detailed crawl, Search Console analysis or implementation would be a separate agreed scope.
Request a free website reviewDuplicate Content: Frequently Asked Questions
I'm a developer who moved into technical SEO. I trace search problems through crawling, rendering, indexing, templates, content and performance, then implement the fixes instead of handing over a generic export. Request a free website review and I'll review your site personally.